
Enabling robots to navigate autonomously through complex, unknown environments as humans do has long been a major challenge in embodied intelligence. Human navigation depends on the interplay of multiple forms of intelligence: common sense and semantic understanding tell us that a nonstick pan is more likely to be found in a kitchen; logical reasoning helps us infer that a small, blurry red dot in the distance is a red flag; spatial perception and reasoning allow us to relate a two-dimensional map to the real three-dimensional environment and determine our position even without GPS; and long-, medium-, and short-term memory help us remember routes we have traveled, understand the progress of the current task, and use external tools to obtain information and support decisions. Beyond individual intelligence, humans also have strong capabilities for group collaboration: through communication, we break down complex tasks, divide work according to each member’s strengths, and share information, coordinate actions, and dynamically adjust plans during execution. Together, these capabilities—from individual autonomous decision-making to collective intelligent collaboration—constitute the central challenges facing robots on the path toward general intelligence.
In recent years, the rapid development of multimodal large models and agent technologies, particularly the emergence of GPT-6 Astra, has brought increasingly strong capabilities in visual understanding, logical reasoning, spatial cognition, and tool use. But when these capabilities are applied to robot navigation, how far can GPT-6 Astra actually go? How far is it from human-level general-purpose autonomous navigation? To investigate, we explored three representative and challenging navigation and collaboration tasks:
(1) Long-distance navigation in an open world with weak priors. When people are given a satellite image, a hand-drawn map, or even a simple topological map, can they reach a destination using only these imprecise maps, without GPS, prior mapping, or any external localization? This task focuses on whether an agent can connect an abstract two-dimensional map to a real three-dimensional environment and autonomously navigate hundreds of meters or even kilometers through a city without precise global localization.
(2) Long-horizon autonomous target search in a completely unknown environment. When people enter an unfamiliar building for the first time, they can use common sense, environmental cues, and spatial reasoning to find destinations such as kitchens or restrooms, even without any prior information. For robots, this requires not only understanding the current environment but also continuously exploring unknown spaces, maintaining historical memory, and dynamically adjusting search strategies. We aim to test whether a large model can truly achieve autonomous exploration and long-horizon navigation when given only a goal, with no specified route.
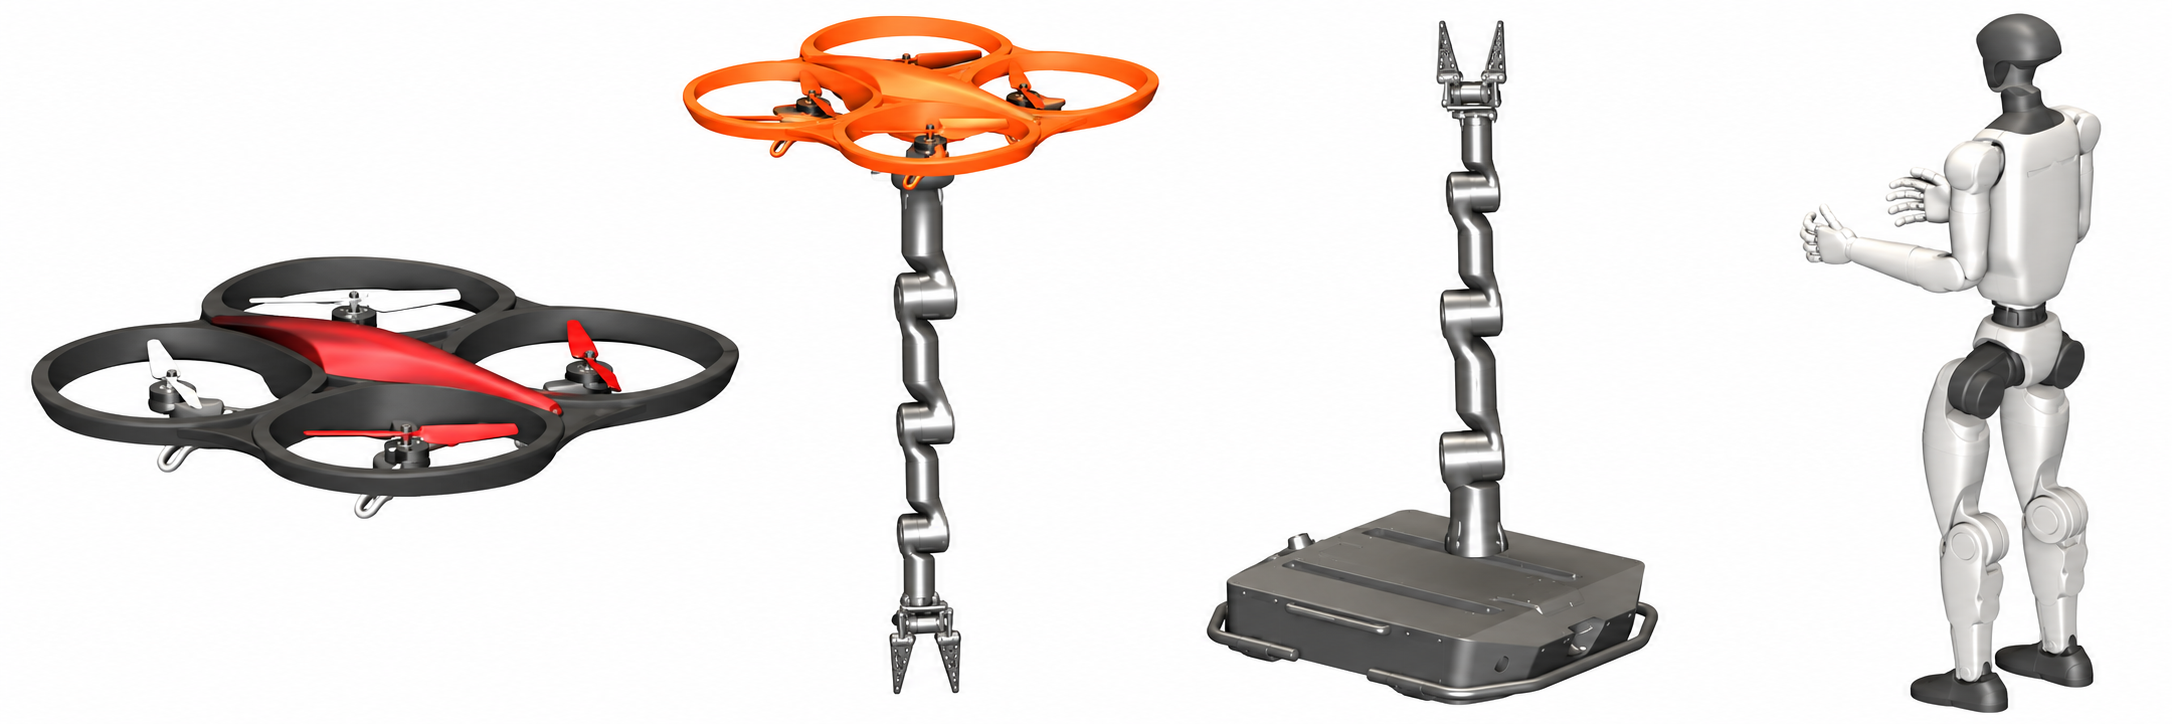
(3) Heterogeneous robot team collaboration on complex, open-ended tasks. How do the challenges grow when a single robot becomes a team of robots with different capabilities? We introduce four types of heterogeneous robots—a flying robot, an aerial manipulator, a mobile manipulator, and a humanoid robot—and ask them to jointly understand complex tasks, negotiate roles, share information, and work together in dynamic environments to complete open-ended tasks involving search, manipulation, repair, and delivery.
We observed several interesting phenomena in our experiments. In the first task category, GPT-6 Astra + Codex already demonstrated strong map understanding and spatial reasoning, connecting two-dimensional maps to three-dimensional environments and guiding long-distance navigation. In the second category, involving completely unknown environments, directly calling the GPT-6 Astra model API was prone to issues such as repeated exploration and unstable decisions due to insufficient historical memory and difficulties in context management. In the third category, involving multi-robot collaboration, the system also had to handle information synchronization, task decomposition, capability allocation, and changes in a dynamic environment; relying solely on direct decisions from GPT-6 Astra was often insufficient for stable, efficient team collaboration.
This raises a deeper question: is the bottleneck in general-purpose robot intelligence the capability of the foundation model itself, or the way we build a reliable agent system—an Agent Harness—around it? Furthermore, can we use the model’s own reasoning and programming abilities to let agents continually identify problems, optimize their architecture, and achieve Recursive Self-Improvement (RSI)?
1. Long-distance navigation with weak priors
CityWalk Like a Human
When people arrive at a zoo and receive a map, they can work out how to reach the aquarium. Maps are an important, high-value prior for navigation tasks [1]. However, obtaining high-precision maps that provide accurate coordinates and semantic information is often difficult. Abstract maps, such as the one in Figure 1, are much more common in everyday life. We call this problem long-distance autonomous navigation in an open world with weak priors: given only an abstract map, an agent must autonomously complete a long-distance urban navigation task, traversing intersections, streets, walkways, and open areas without GPS, prior mapping, or any external localization.
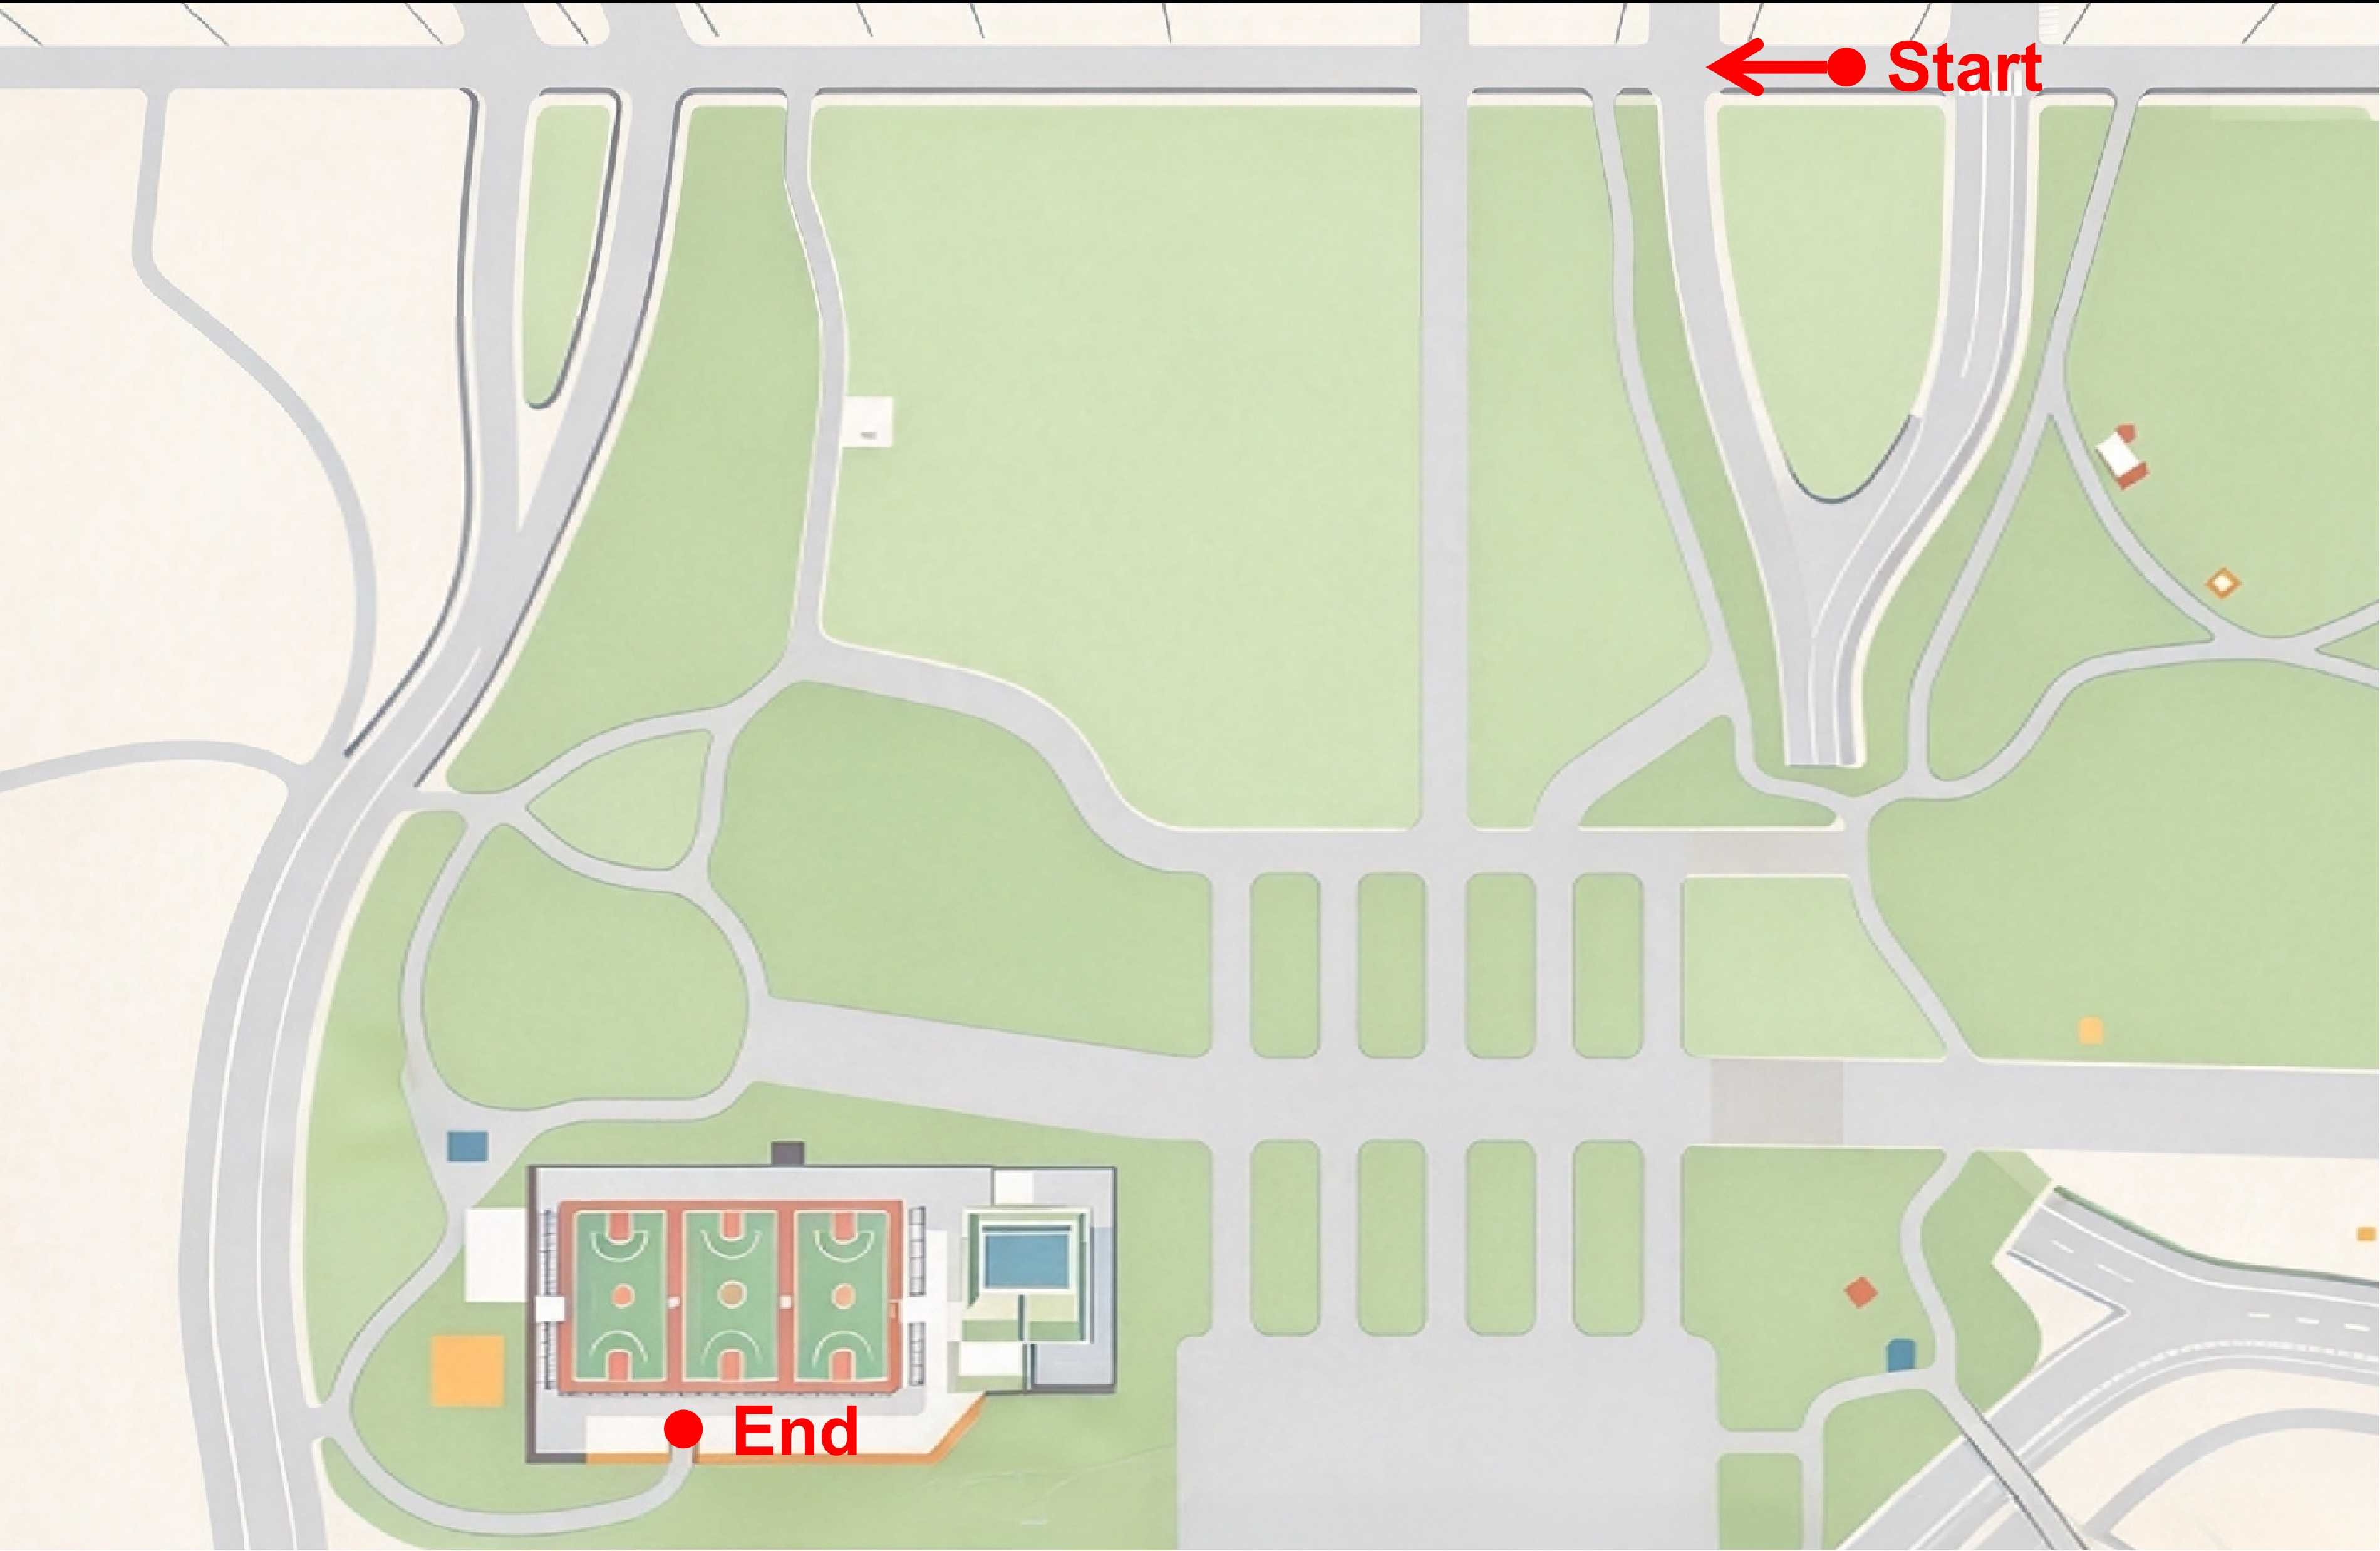
Our earlier work, PathPainter [2], focused on deriving global path plans from maps. It combines powerful image generation models such as Nano Banana / GPT Image with the conventional A* path planning algorithm to perform global path planning. During execution, however, it still relies on global localization and lacks an understanding of the surrounding environment.
Two Paths to Intelligence: Emergence or Design?
As GPT-6 Astra advances across a wide range of fields, we are curious: although Astra has shown enormous potential in some tasks, can it continue to operate reliably over truly long-horizon urban navigation? Is a more powerful foundation model the only answer? We used GPT-6 Astra Ultra + Codex (hereafter “GPT”) to run the task shown in Figure 1 fully autonomously in simulation.
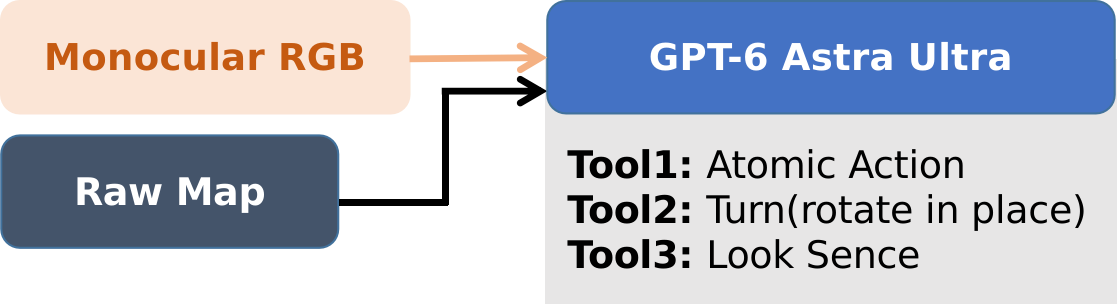
The results showed that GPT completed the same task with a success rate of nearly 100%, displaying remarkable autonomy and intelligence. Using a monocular RGB camera, it chose to retreat when it reached impassable areas, observe and explore when the map differed from reality, and seek landmarks to localize itself when its position was unclear.
However, behind this striking success rate, the costs and limitations of this approach are equally clear. First, GPT’s trajectories are often inappropriate: it frequently scrapes against or even moves over obstacles. This may be harmless in simulation, but in the real world, every collision carries substantial costs in hardware damage and safety risks. Second, the high inference costs and unpredictable latency of general-purpose large models make it difficult to meet the real-time requirements of physical robots. Third, the behavior of a closed-source foundation model is a black box: we cannot explain its decision-making process, much less constrain it.
To address these limitations, we built a navigation agent based on the open-source model QWEN 3.8 Next Flash. It likewise needs no global localization and can move freely through a city as a human would. We use four cameras and a ranging sensor. The continuous input from four camera views places substantial pressure on the context window and requires the agent to accurately track task progress, promptly understand environmental changes, and adjust its actions. As shown in Figure 3, the system has a hierarchical architecture inspired by fast and slow systems. The upper level plans a global path using an improved version of PathPainter [2]. At the lower level, a Subgoal Agent executes subgoals, while a high-frequency Monitor Agent checks in real time whether the current subgoal has been completed. The Subgoal Agent calls NavDreamer [3] as its World Action Model.
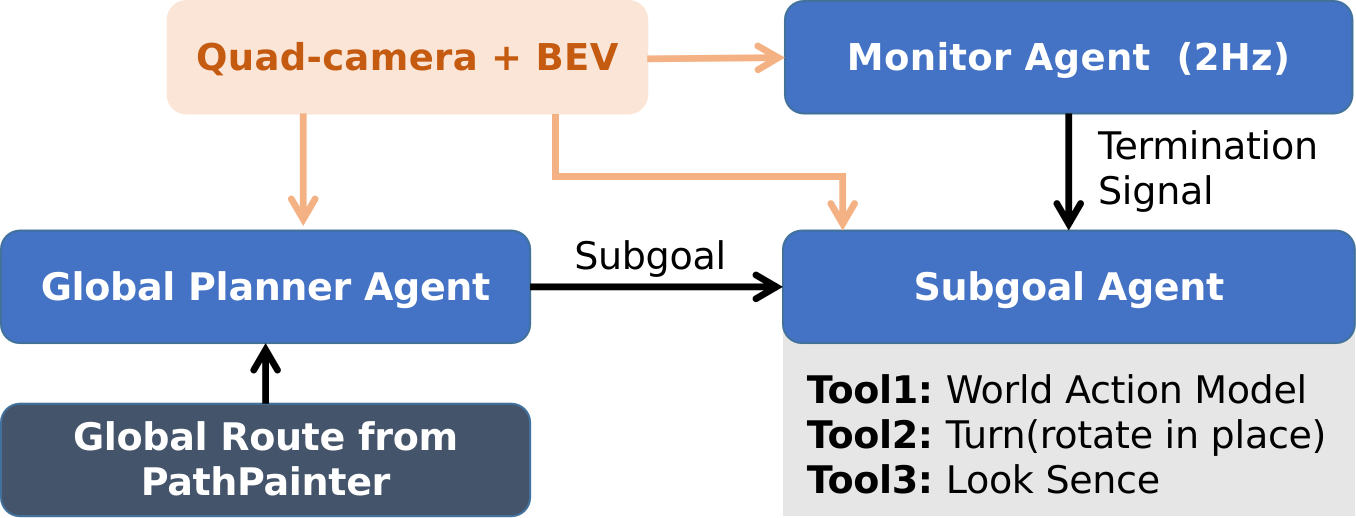
On the task shown in Figure 1, this system reliably follows a 570 m route from one corner of the map to the basketball court entrance at the opposite corner, passing through roads, walkways, plazas, and stairs. Compared with GPT, its trajectories are smoother, steadier, safer, and more consistent with social norms.
The Convergence of Intelligence
The hierarchical architecture is controllable and interpretable, but depends on extensive manual design and tuning; its capability boundaries are explicitly defined by its designers. Using only monocular RGB input, GPT completed the same task in simulation with a success rate close to 100%, demonstrating retreat, exploration, and autonomous localization. However, its decision-making process is not interpretable, and the stability of its behavior remains difficult to guarantee. This 570 m simulation test suggests that foundation models and harness designs from leading AI companies are rapidly encroaching on the capability boundaries of manually engineered architectures.
Success in simulation must still be tested against real environments, inference latency, API costs, and long-tail failures. Next, we will deploy both systems on physical robots for comparison and explore their integration: a foundation model serving as the “brain,” with a World Action Model acting as a controllable, high-frequency “cerebellum,” so that general intelligence and interpretable architectures can complement each other. We believe that the real, noisy, and ever-changing world may be the ultimate test.
Research authors: Yijin Wang, Tianyang Chen, Shaokai Jin
An arXiv preprint is coming soon.2. Long-horizon navigation in unknown environments
Specify “What to Find,” Without Specifying “How to Get There”
We make this task setting more challenging. Imagine entering an unfamiliar shopping mall for the first time: even without knowing the exact location of the restroom, a person can search using common sense, the spatial layout, and signage [4]. This reflects an important capability: autonomously finding a target through common sense and visual observation when the goal is clear but the environment is unknown. In recent years, some vision-and-language navigation work has continued to focus primarily on following language instructions that include route hints. For example, NaVILA’s real-robot demonstration of navigating to a restroom provides route information in advance, including going around stairs, entering a corridor, and turning right [5]. In contrast, we want a robot in a completely unknown environment to receive only an instruction such as “find the restroom” and independently decide where to explore using common sense and observations on site, without a human describing the route to the destination.
In this setting, we first tried calling the GPT-6-Astra API directly to make navigation decisions. In the experiment, the model’s environmental observations came only from images captured by four cameras, which it combined with the task instruction to decide its next action. Although the GPT-6-Astra API provides strong visual understanding and reasoning capabilities, a lack of historical context can still cause repeated exploration. Simply calling the model and executing its output is therefore insufficient to guarantee successful long-horizon navigation.
From Single-Step Intelligence to Long-Horizon Autonomy
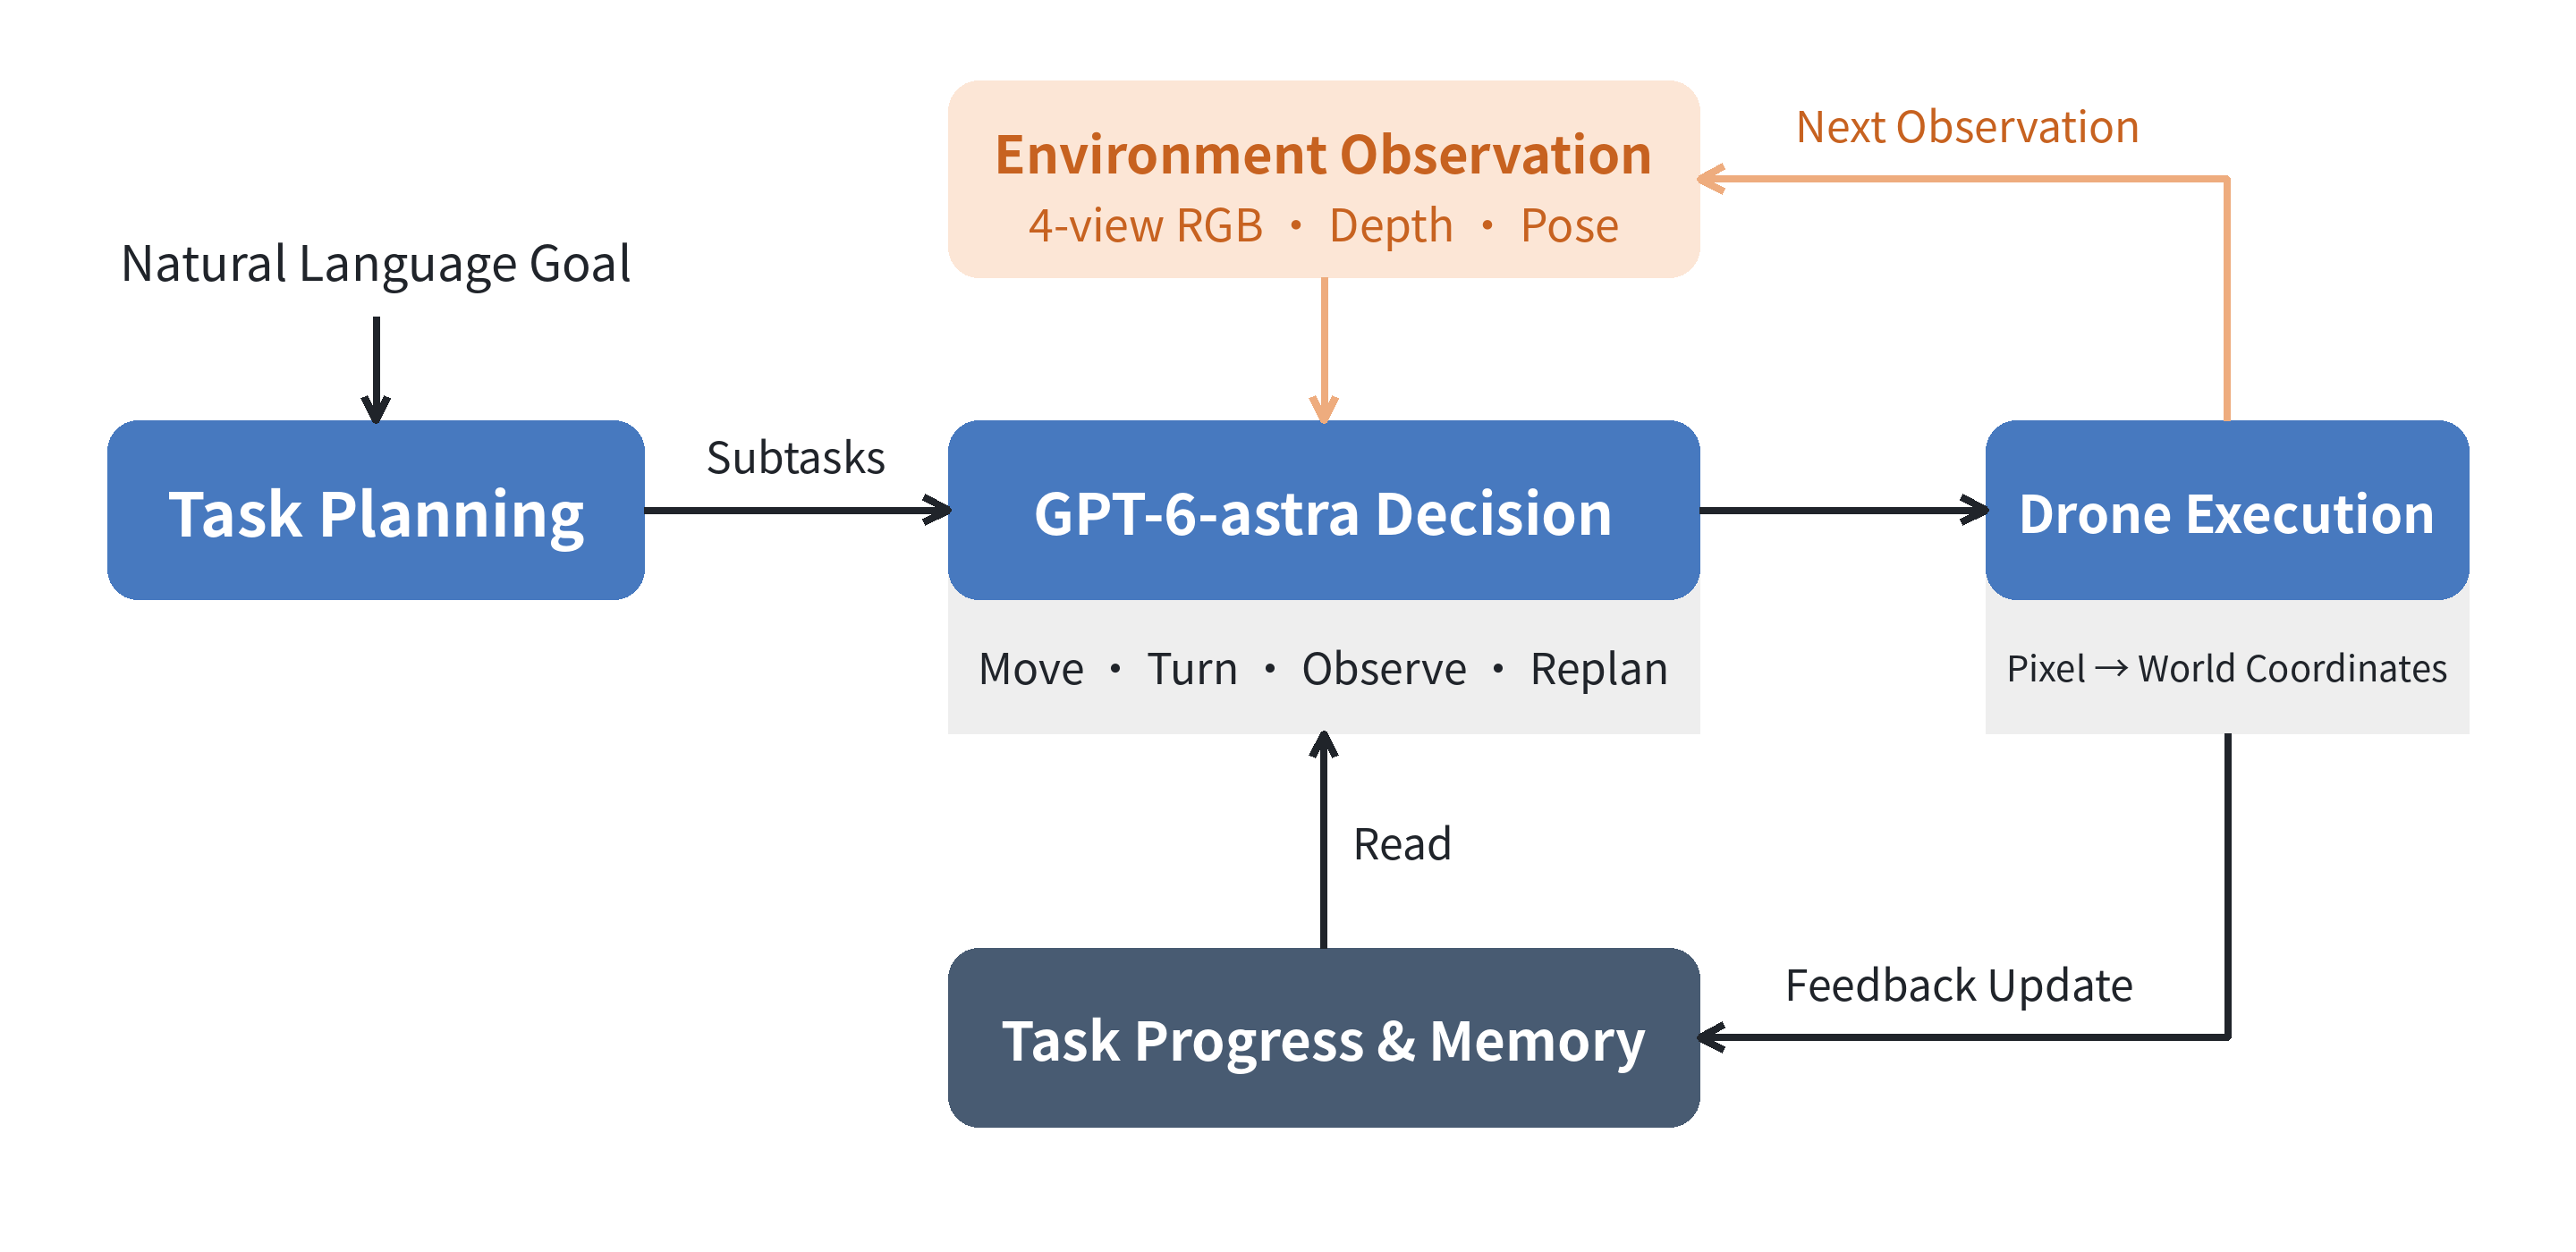
To address this problem, we built a harness for GPT-6 Astra to perform long-horizon autonomous goal navigation in completely unknown environments. The framework focuses on supplying historical context for sequential decisions, allowing the model to build on previous exploration and reduce repeated visits to the same areas. First, the model decomposes the natural-language goal into staged subtasks, and the system saves and maintains task progress. Before each decision round, the system obtains RGB images from the front, right, rear, and left cameras, together with odometry, and uses MoGe-2 to estimate a depth map for each view [6]. The model combines the current images, task progress, historical memory, and feedback from the previous execution to decide whether to move, turn, observe again, or revise the plan. The model directly selects a pixel location in an image as the movement target, which is then transformed into world coordinates using depth and pose. After the drone reaches the target point, the system records target cues, the actual start and end positions of the movement, and the execution result, updates memory and task state, and proceeds to the next decision round. This creates a closed loop of “planning—observation—decision—execution—feedback.”
Taking Autonomous Exploration Further
We conducted experiments in a simulated three-story villa with a total floor area exceeding 300 square meters (Videos 8, 9, and 10). The environment is large, contains many rooms, and has a complex layout requiring route choices between rooms and movement across floors. In this unknown environment, we set navigation tasks such as “find the kitchen on the second floor” and “find the room with pink seat cushions,” requiring the system to explore autonomously and reach the target based on natural-language instructions. Across 12 experiments, the system reached the target successfully in 10, achieving a target-reaching rate of 83.3%. In one “find the kitchen on the second floor” task (Video 9), the system autonomously generated six staged subtasks. During execution, the drone started in a first-floor room, found the stairs, and climbed to the second floor. After discovering that a room on one side was a bedroom, it returned and changed its exploration direction. It eventually identified the kitchen using visual cues such as a sink, worktops, and cabinets, flew into the room, and hovered. The entire process involved 36 calls to the GPT-6-Astra API, completing navigation from exploration of an unknown environment to target confirmation and entry.
Notably, we also conducted exploratory tests with the open-source model Qwen3.8-Flash-Next, keeping the Harness unchanged and replacing only the core model. The system could still complete some navigation tasks, but its overall performance declined. These preliminary results suggest that appropriate context management, memory maintenance, and tool-use mechanisms can help different models handle complex navigation tasks to some extent, while also showing that system performance remains dependent on the capabilities of the core model.
We also conducted exploratory tests combining GPT-6-Astra with Codex and observed that the system could likewise complete some navigation tasks. However, because the internal mechanisms of the underlying model and Harness are difficult to inspect and intervene in directly, we cannot yet further pinpoint performance bottlenecks or carry out systematic optimization.
We are currently introducing RSI to continually optimize the navigation harness, addressing issues such as occasional inaccuracies in determining subtask completion and reduced performance when transferring to other open-source models, such as Qwen3.8-Flash-Next. Based on execution feedback and evaluation results, the system will automatically propose, test, and retain effective improvements to task decomposition and completion assessment, and validate them across different models to improve cross-model generalization. We also plan to deploy the system on physical robot platforms for navigation tests in real environments.
Research authors: Wenjun Li, Jinhan Li, Mo Zhu
An arXiv preprint is coming soon.3. Heterogeneous robots, working as a team
When Intelligence Extends Beyond the Individual
What happens when a single-robot task becomes a multi-robot team task? Imagine a maintenance team entering a factory that has stopped production, with only the instruction to “repair the equipment, make the product, and deliver it to the delivery station.” The equipment and materials must still be located on site; team members exchange clues, divide work according to their expertise, and adjust their arrangements as circumstances change. We envision a heterogeneous robot team—a reconnaissance drone, an aerial manipulator, a mobile manipulator, and a humanoid—collaborating in the same way: the drone finds a repair kit, the mobile manipulator retrieves and transports it, the humanoid takes over installation, and the aerial manipulator searches for raw materials at the same time. Only once the equipment is repaired and the materials are ready can the team connect power and begin production.
Our earlier D-VLC work [7] established a distributed robot team that searches collaboratively for open-ended targets. Video 11 shows the robots sharing visual cues, collaborating to open a door, and continuing their search. However, the tasks were not yet sufficiently complex or varied, and the range of robot types was limited.
Now, we want a wider variety of robots to sustain handoffs in unknown environments and complete more complex tasks involving repair, manufacturing, and delivery. They must not only find objects but also arrange who acts first, who takes over, and which work can proceed in parallel. We therefore expanded the team to four robot types: a drone, an aerial manipulator, a mobile manipulator, and a humanoid, as shown in Figure 5.
In this more challenging setting, we first tried having GPT-6 Astra directly decide the next actions of all four robots. In each round, the model reads the overall task, the four camera views, the observed map, and execution feedback, then produces local actions. The execution results are fed back to the model. As shown in Video 12, the robots frequently stop after moving a short distance. All four views repeatedly show them waiting for the next instruction or model response, while the shared map expands slowly. Even at 20× playback speed, the pauses between movements remain apparent. After 15 minutes, the system had confirmed only the location of the delivery station and had not yet reached repair, material preparation, or production. Under this experimental configuration, generating local actions one round at a time did not establish the exploration and division of labor needed for sustained task progress.
Self-Evolution of the Multi-Agent Framework May Be the Answer
To address slow task progress when directly generating actions, we built on D-VLC’s multi-robot agent architecture to develop a distributed collaboration framework with asynchronous execution. Each robot identifies targets from RGB images and updates the shared map with its discoveries. The task model decomposes the overall instruction into subtasks and assigns them, while the system continuously records task progress and robot states. Perception, reasoning, and actions proceed asynchronously: while one robot waits for recognition or planning results, the others can continue reasoning and working independently. After an operation, the system updates its state using the success or failure feedback and schedules subsequent tasks.
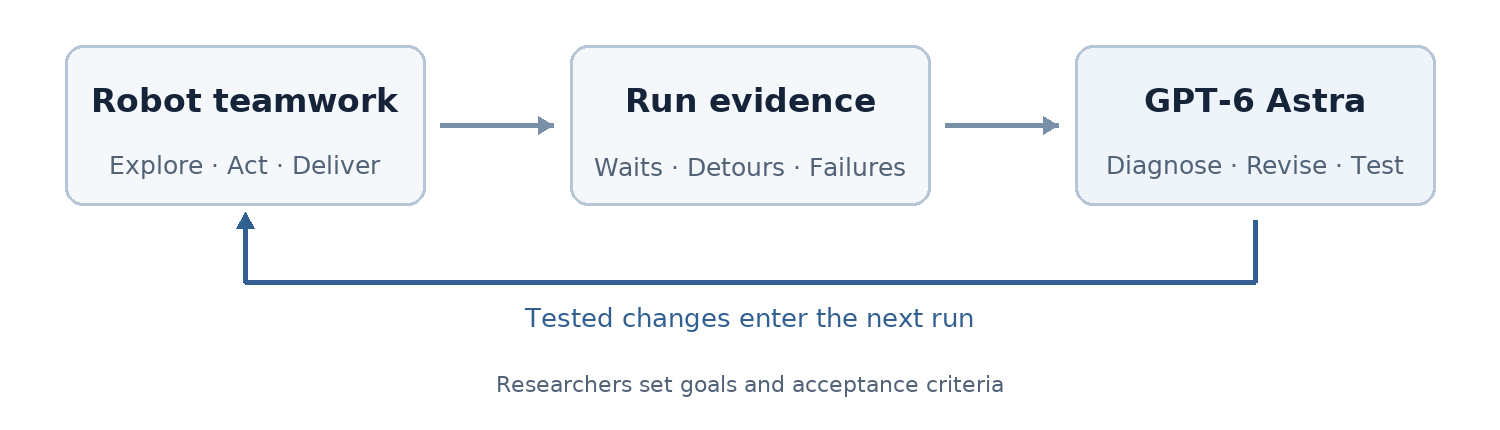
Building on this framework, we draw on RSI to let GPT-6 Astra continually improve the collaboration system. As shown in Figure 6, after each experiment, it examines videos and logs to identify repeated exploration, long waits caused by blocked action-reasoning requests, and mismatches between robot capabilities and subtask decomposition or assignment. It then modifies the relevant code. Targeted unit tests check the changes before the full task is run again to evaluate completion time, parallel collaboration, and the smoothness of motion and manipulation. Changes that improve collaboration and efficiency while passing functional checks are retained; changes that provide no benefit are reverted. Researchers set improvement goals for exploration efficiency, recognition accuracy, and task allocation, constrain the scope of code changes, and inspect the results. Problems exposed in each run thus become concrete changes and validation steps, gradually improving exploration, division of labor, and execution. After these iterations, the system completed search, repair, production, delivery, shutdown, and power disconnection in the factory (Figure 8 and Video 14), demonstrating how continual improvements to the collaboration framework can put model capabilities to work on complex tasks.
Autonomous Collaboration Through Collective Intelligence
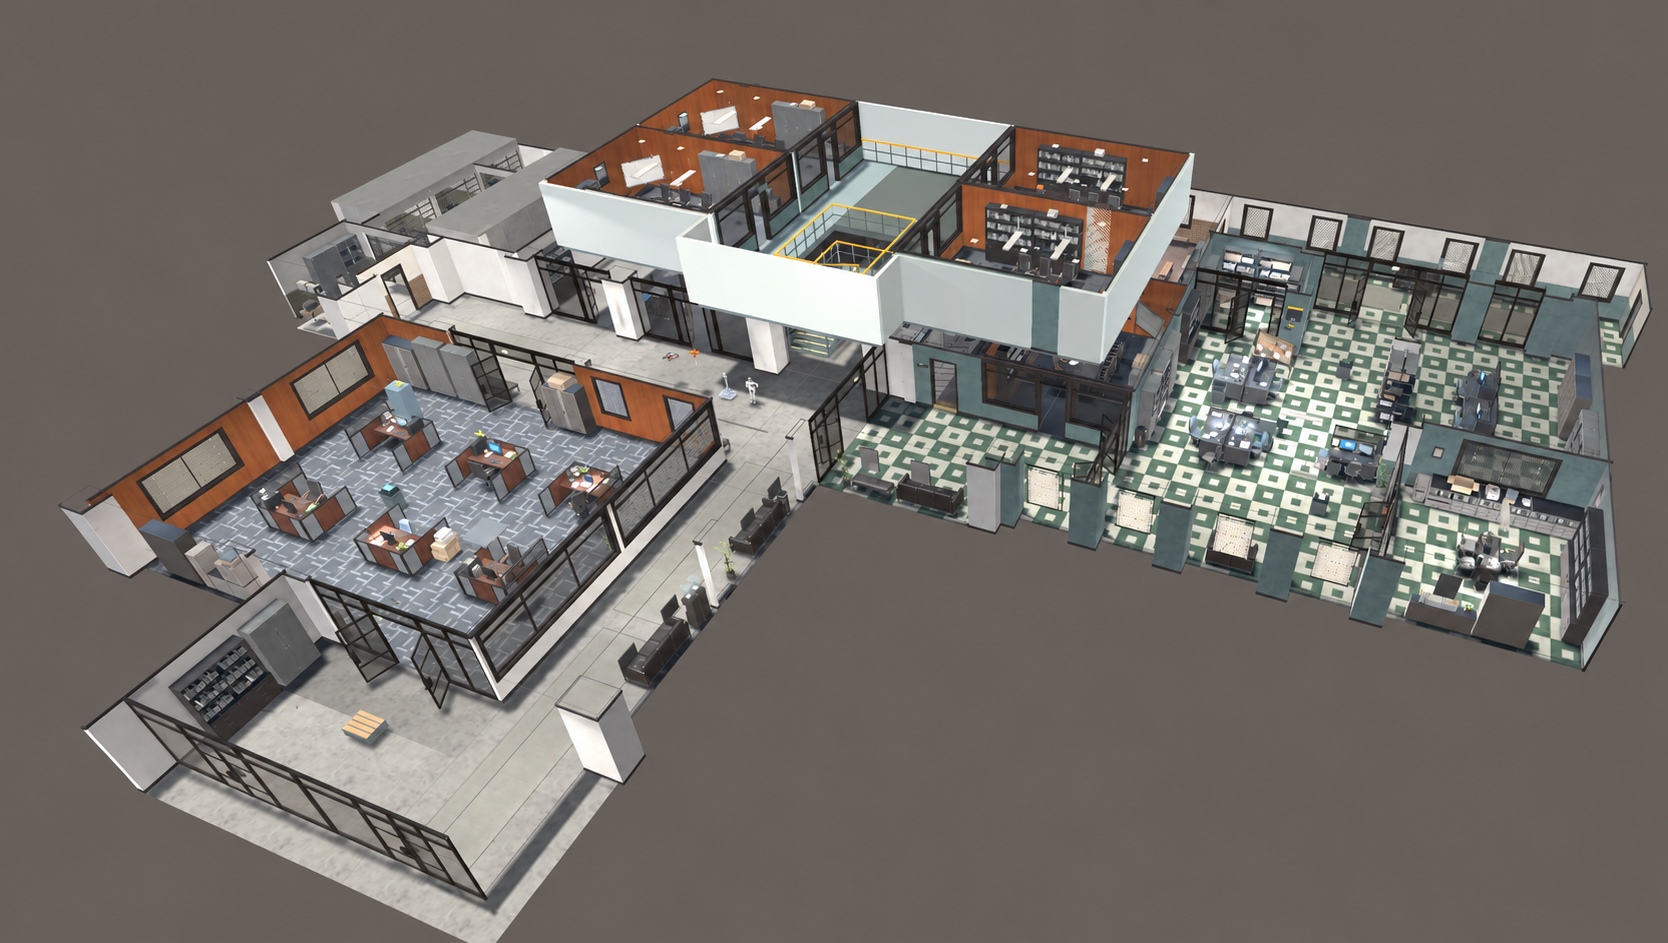
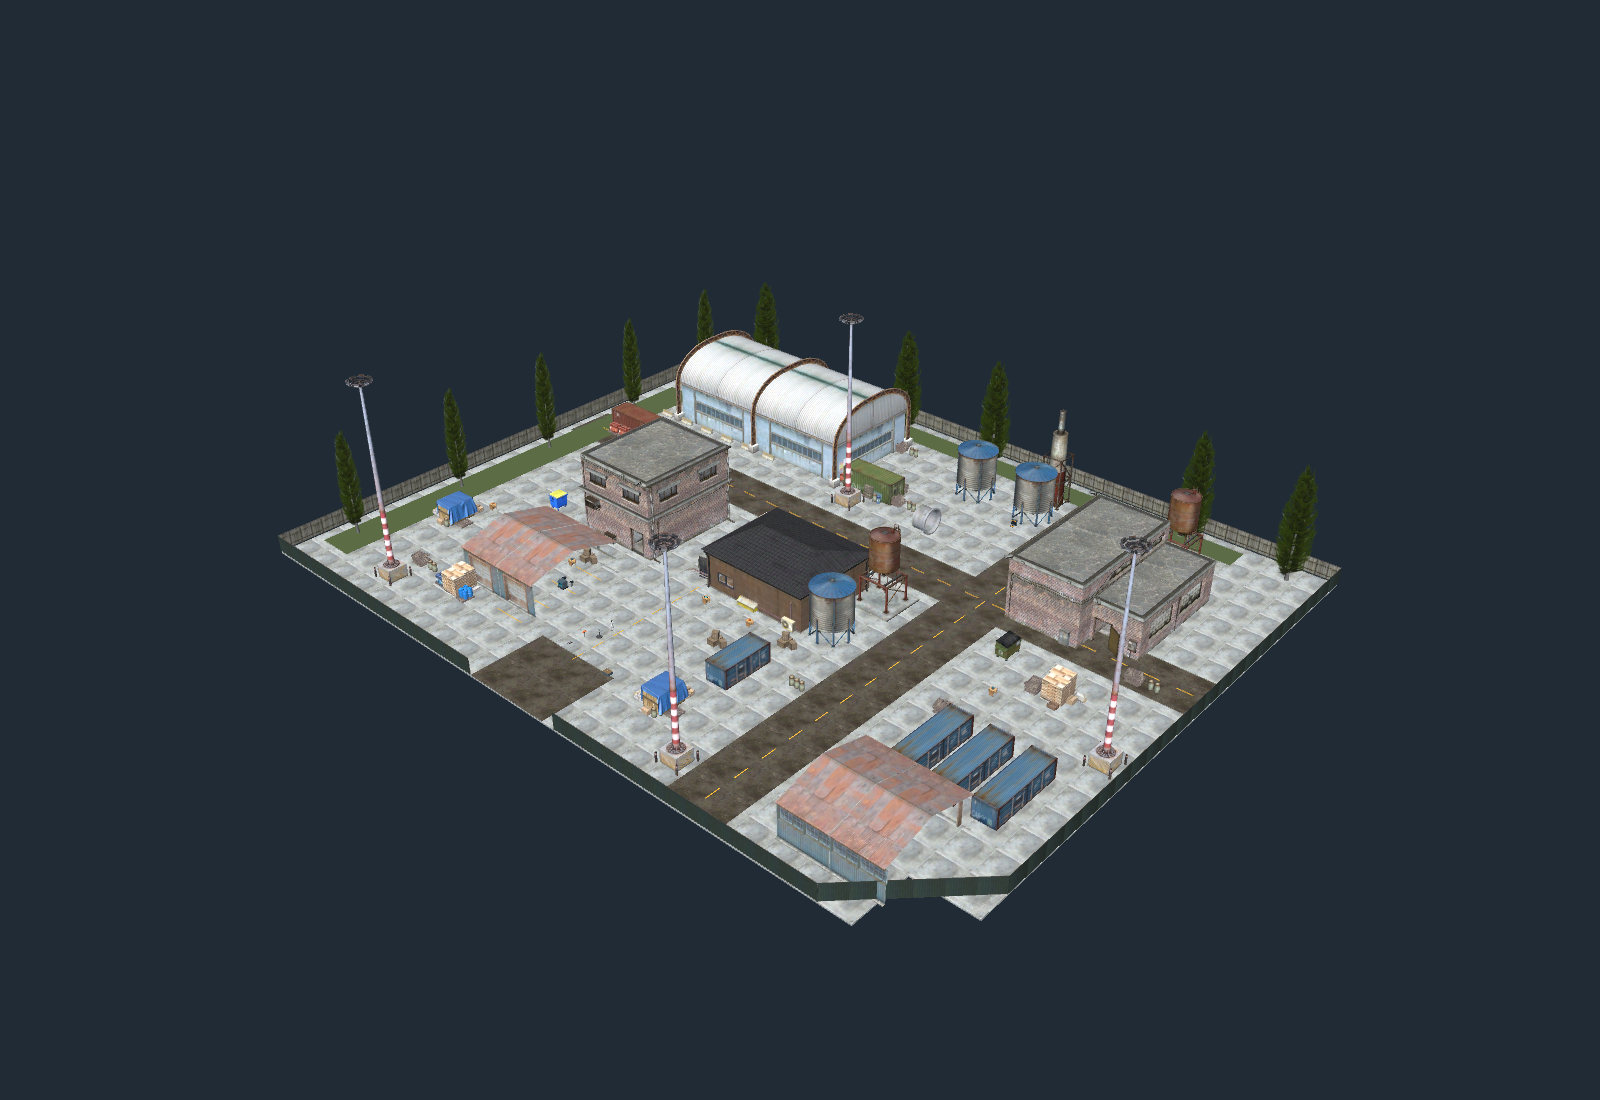
Using the same Agent Harness, we completed four-robot collaboration experiments in two very different simulated settings: a two-story indoor police station (Figure 7 and Video 13) and an outdoor factory (Figure 8 and Video 14). The results on these two open-ended tasks demonstrate zero-shot transfer of the architecture.
In the two-story police station task, the mapped area measures approximately 50 × 50 meters. With no prior map, the robots must carry out a series of search, manipulation, and collaboration tasks in a completely unknown environment, ultimately delivering spare keys according to a work order. The task requires finding nine initial target categories: the work order, key cutter, console, service key, authorization box, power supply, delivery station, repair module, and key blanks. The team must complete exploration, material selection, equipment isolation and repair, coordinated machine startup, key inspection, delivery, and power disconnection in the required order. It must also use on-site feedback to select the correct materials and objects to operate.
Video 13 shows an example of successful execution. After the relevant objects are found, the humanoid retrieves the authorization box needed for machine startup, the mobile manipulator retrieves a key blank and loads it into the key cutter, and the aerial robots continue exploring while remaining available to help. Shared maps of both floors display each member’s location and discoveries. In the full test, the four robots performed 78 successful exploration operations and 24 successful non-exploration operations, completing the task in 14 minutes and 48 seconds.
The factory collaboration task covers approximately 100 × 80 meters, including both indoor and outdoor areas. Again, none of the robots has a prior map, so the task requires strong collaborative exploration and object recognition and localization. To manufacture one valve-pipe assembly, the team must locate seven target categories—the assembly machine, console, delivery station, repair kit, power supply, pipe, and valve—and complete approximately 12 manipulation subtasks in a logically constrained order, including object search, equipment repair, material transport, and delivery of the finished assembly.
Video 14 shows an example of successful execution. The four robots initially spread out to explore. At approximately six seconds into the video, the mobile manipulator finds a valve and brings it to the machine while the humanoid searches for and transports a pipe in parallel. The humanoid then brings the repair kit to the machine for repair. The drone and aerial manipulator explore together and connect power after locating a supply, allowing the machine to begin production. Finally, the humanoid retrieves the finished assembly and takes it to the delivery station. In the full test, the four robots performed 150 successful exploration operations and 12 successful non-exploration operations, completing the task in 12 minutes and 50 seconds.
To further test robustness and adaptability, we also interrupted an ongoing task and introduced a new requirement. As shown in Video 15, after repair and preparation of the first set of materials but before power was connected, we changed the factory order from one valve-pipe assembly to two. When the order-change notice appears, the team reconsiders the subtasks needed for the new goal. It reasons that the available materials are insufficient for two assemblies and resumes exploration to find another pipe and valve. Once these are found, the humanoid transports the additional materials. The team preserves the completed repair and material preparation, adds the materials needed for the second assembly, and resumes production. It ultimately delivers both assemblies, shuts down the machine, and disconnects power. These excerpts show how the robots divide work, hand off tasks, and build on existing progress when the goal changes.
These results demonstrate the possibility of robot teams completing complex work together: in completely unknown environments, members search for clues, share progress, and use their respective capabilities to perform retrieval, transport, manipulation, and manufacturing in a distributed manner, completing the overall task within a finite time. The framework transfers zero-shot between the different workflows in the factory and police station, also showing that by maintaining task dependencies and execution feedback, a collaboration framework can organize model capabilities into team actions that make sustained progress across scenarios. This provides a direction for our continued use of GPT-6 Astra-assisted RSI: accumulating evidence for improvements from each experiment and gradually adapting to longer tasks with more changes. Future work will continue RSI-style iteration to improve task efficiency and adaptation across environments, support heterogeneous robots dynamically joining or leaving the team and further task changes, and conduct physical experiments.
Research authors: Yuan Zhou, Ruitong Lin, Xingxing Li, Shen Wang, Mo Zhu
An arXiv preprint is coming soon.Conclusion
The results from long-distance navigation with weak priors, reasoning-based navigation in completely unknown environments, and distributed heterogeneous multi-robot collaboration indicate that GPT-6 Astra already possesses the complex reasoning and spatial understanding capabilities needed for general-purpose navigation. As tasks become more complex—for example, when coordinating multiple heterogeneous robots—they place greater demands on both model capabilities and the completeness of the Agent Harness. The emergence of GPT-6 Astra makes workflows spanning data, training, and closed-loop execution more flexible. Visual understanding and high-level decision-making that once required specially trained VLAs and complex engineering modules may now be achievable with general-purpose models combined with the memory, task management, and execution feedback provided by a harness. At the same time, the models’ ability to understand complex systems, modify code, and run automated tests [8] makes RSI a research direction worth exploring [9] [10]: it can accelerate engineering iteration and may also allow systems to gradually develop the ability to improve themselves. What truly merits research may be the problems that cannot easily be displaced by increases in model scale and capability, together with broadly applicable methods for solving them.
Across these three types of tasks, several opportunities remain to improve GPT-6 Astra and the systems built around it. In long-distance navigation with weak priors, priorities include safer trajectories that better follow navigation norms, lower inference costs and latency, and more interpretable and controllable decisions. In autonomous exploration of completely unknown environments, more effective historical memory and context management are needed to reduce repeated exploration and improve task decomposition and the accuracy of subtask completion checks. In heterogeneous multi-robot collaboration, priorities include more reliable tracking of task dependencies and shared progress, better matching of tasks to robot capabilities, more efficient parallel scheduling, and replanning after failures to better accommodate task changes and robots dynamically joining or leaving the team. These improvements depend on both foundation-model capabilities and how effectively the Agent Harness organizes memory, planning, execution, and feedback. RSI offers a promising direction for continually improving the coordination between the model and its supporting framework.
References
[1] Li, Anqi, et al. "Urbanvla: A vision-language-action model for urban micromobility." arXiv preprint arXiv:2510.23576 ↗ (2025).
[2] Wang, Yijin, et al. "PathPainter: Transferring the Generalization Ability of Image Generation Models to Embodied Navigation." arXiv preprint arXiv:2605.07496 ↗ (2026).
[3] Huang, Xijie, et al. "Navdreamer: Video models as zero-shot 3d navigators." IEEE Robotics and Automation Letters (2026).
[4] Shah, D., et al. Navigation with Large Language Models: Semantic Guesswork as a Heuristic for Planning. CoRL, 2023.
[5] Cheng, A., et al. NaVILA: Legged Robot Vision-Language-Action Model for Navigation. RSS, 2025.
[6] Wang, R., et al. MoGe-2: Accurate Monocular Geometry with Metric Scale and Sharp Details. NeurIPS, 2025.
[7] Zhou, Yuan, et al. "D-VLC: Decentralized Vision-Language Collaboration for Heterogeneous Embodied Multi-Robot Systems in Unknown Environments." arXiv preprint arXiv:2607.29009 ↗ (2026).
[8] Yang, John, et al. "SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering." Advances in Neural Information Processing Systems 37 (2024): 50528-50652.
[9] Zhang, Jenny, et al. "Hyperagents." arXiv preprint arXiv:2603.19461 ↗ (2026).
[10] Jenny Zhang, et al. "Darwin Godel Machine: Open-Ended Evolution of Self-Improving Agents." arXiv preprint arXiv:2505.22954 ↗ (2025).